What is LoRA?
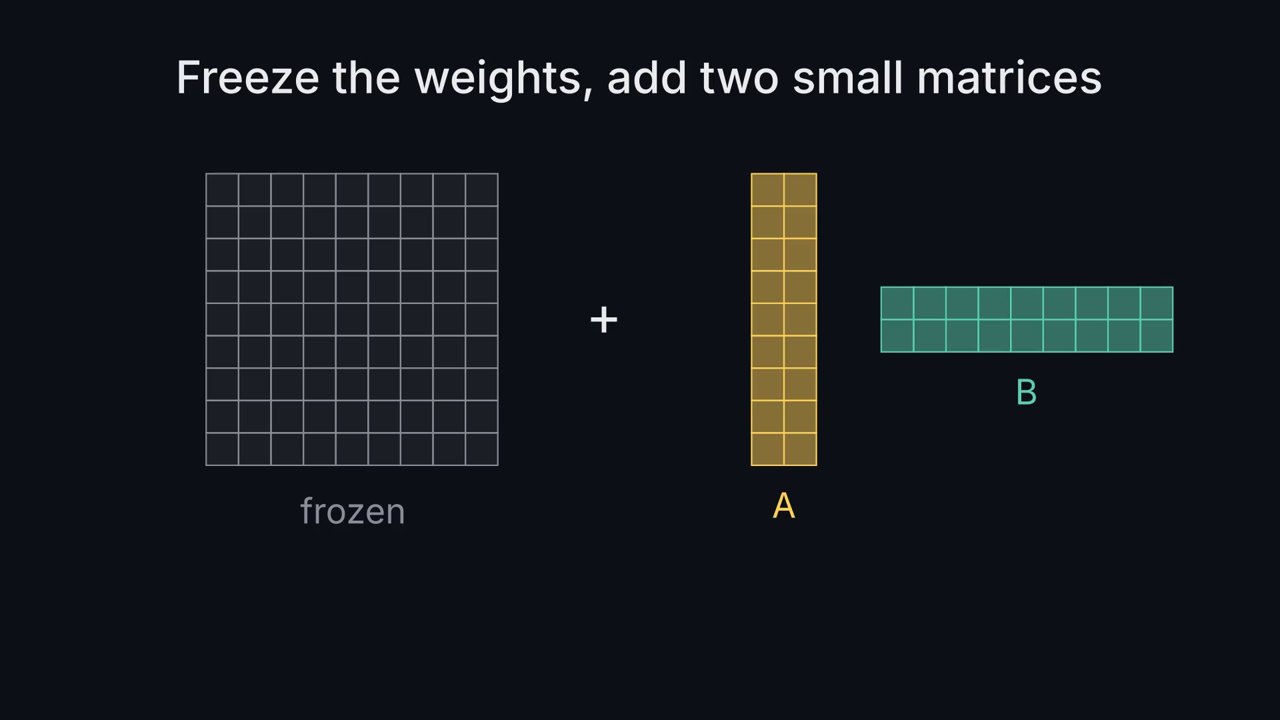
LoRA keeps the original model weights frozen and introduces small trainable low-rank matrices into selected layers. Only these added parameters are updated during fine-tuning.
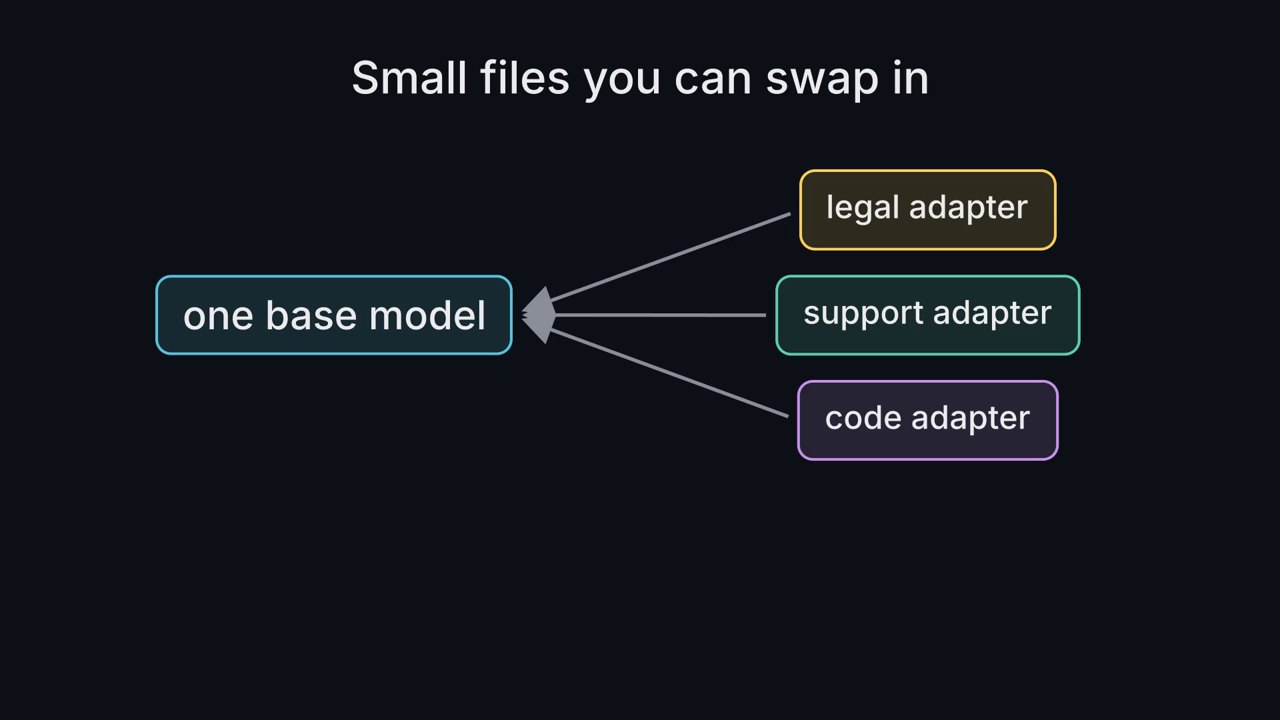
This greatly reduces memory and storage requirements compared with updating the complete model. Multiple LoRA adapters can also be created for different tasks while sharing the same base model.
Read the short notes and pictures.Do everything inside a blue frame.
What is LoRA?
LoRA stands for low-rank adaptation. It is a way to fine-tune a large model for a new job without retraining all of it. The original model is left untouched, and a small set of new numbers is trained beside it. The result is a tiny file, called an adapter, that changes how the big model behaves.
How LoRA works
Freeze the model
The billions of original weights are locked. They do not change.
Add two small matrices
Next to each chosen layer, LoRA adds two thin matrices, usually called A and B.
Train only those
Training adjusts A and B only: often well under one percent of the model’s size.
Combine at run time
The model’s output is its original weights plus the small correction from A and B.
The words you will meet
Fine-tuning
Training an existing model further on your own examples.
Adapter
The small file LoRA produces. It can be loaded or removed at any time.
Rank
How thin the two matrices are. A lower rank means a smaller, cheaper adapter.
Where it is used
Teaching a model your company’s tone or format
Custom styles for image generators
Fine-tuning on a single graphics card
Serving many customers from one base model
Keep these
- LoRA fine-tunes a model by training a small add-on, not the whole model.
- The original weights stay frozen.
- The result is a small adapter file that can be swapped in and out.
- It makes fine-tuning far cheaper and faster.